SynQA
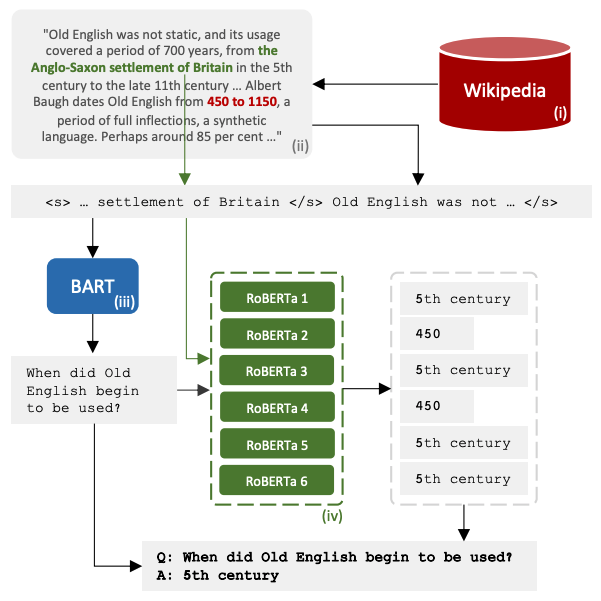
A synthetic dataset of 315k QA pairs on passages from SQuAD designed to help make QA models more robust to human adversaries. This resource is also available in HuggingFace datasets at https://huggingface.co/datasets/mbartolo/synQA.
AdversarialQA (from Beat the AI)
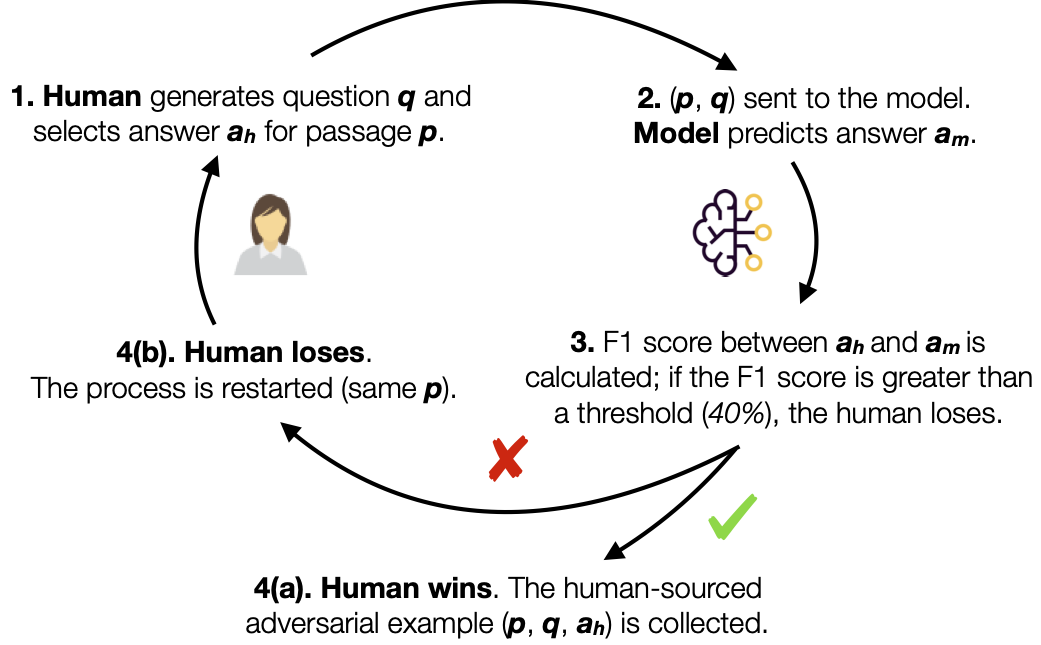
A dataset of 36k challenging extractive QA pairs consisting of training, evaluation and test data collected using three different models-in-the-loop: BiDAF, BERT and RoBERTa.
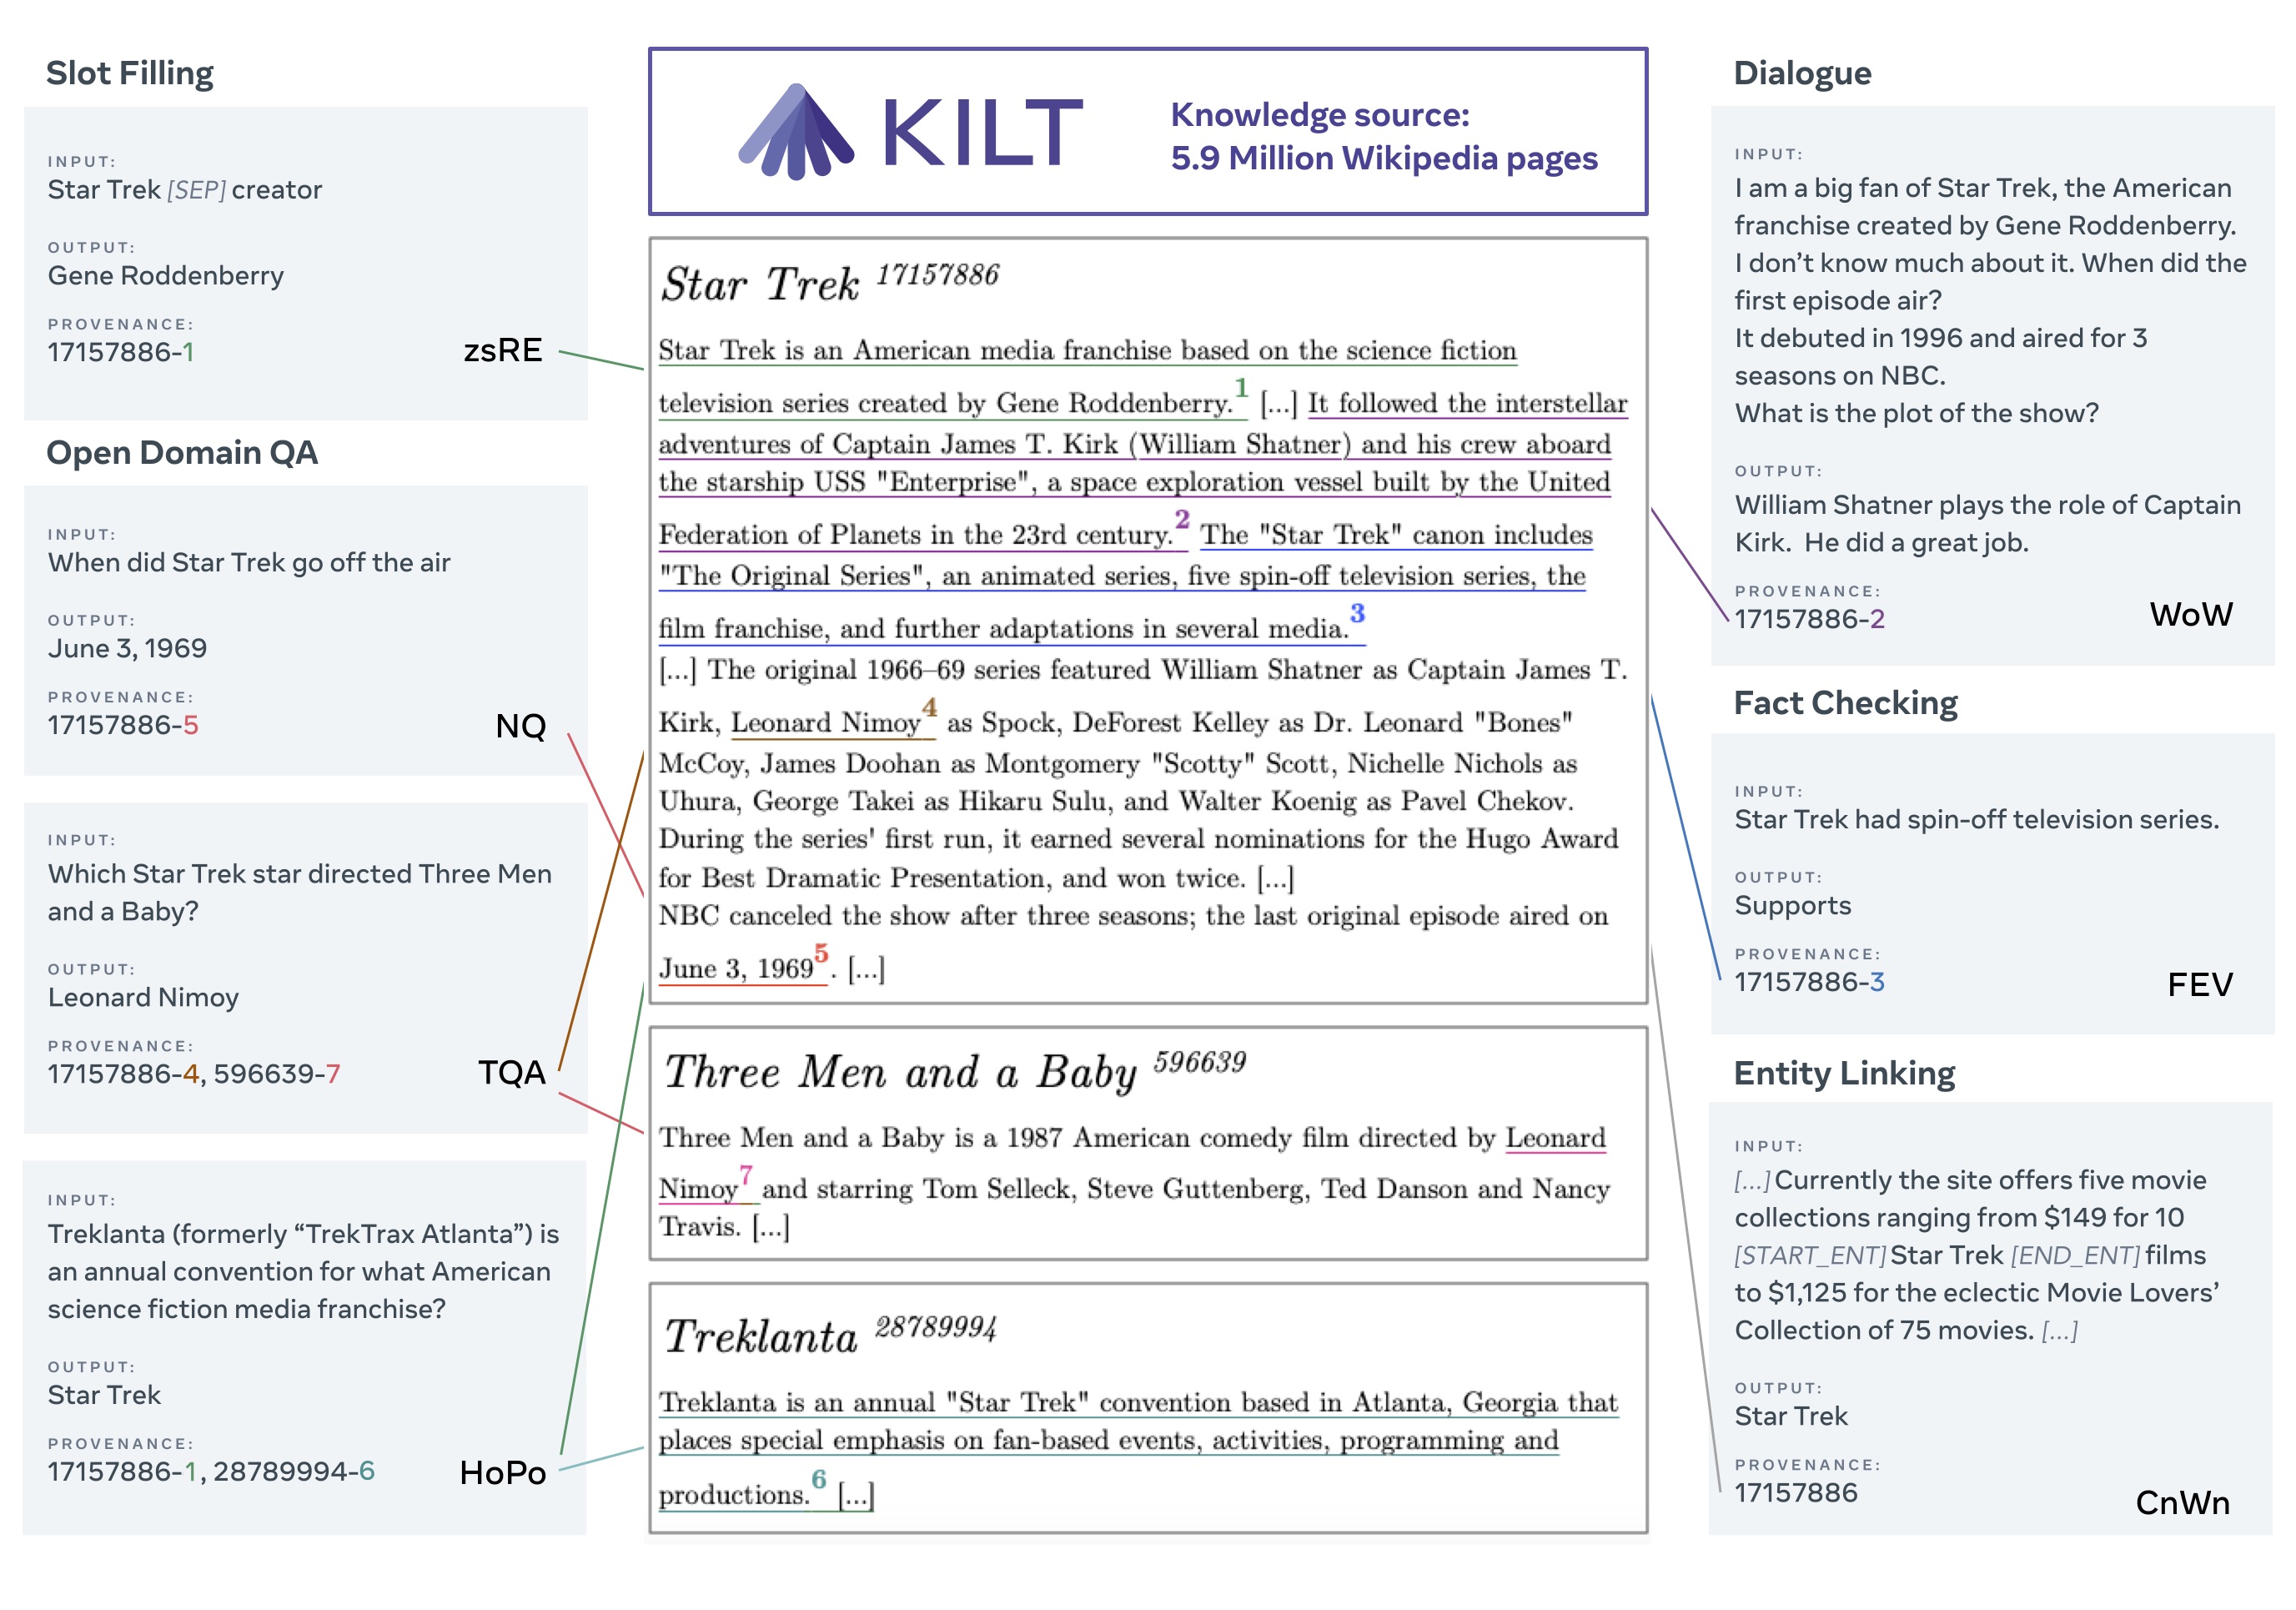
KILT: a Benchmark for Knowledge Intensive Language Tasks
A resource for training, evaluating and analyzing NLP models on Knowledge Intensive Language Tasks. KILT has been built from 11 datasets representing 5 tasks.
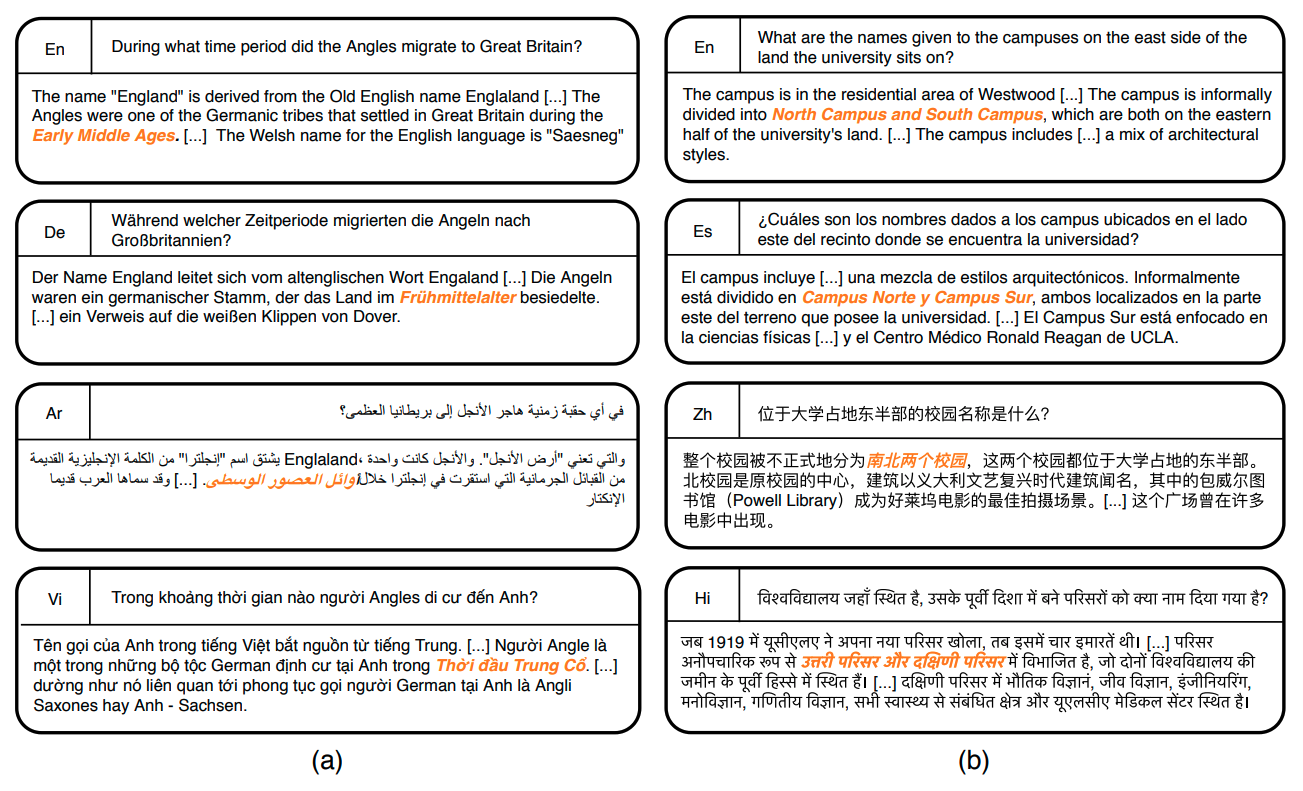
MLQA
A multi-way aligned extractive QA evaluation benchmark MLQA contains QA instances in 7 languages, English, Arabic, German, Spanish, Hindi, Vietnamese and Simplified Chinese.
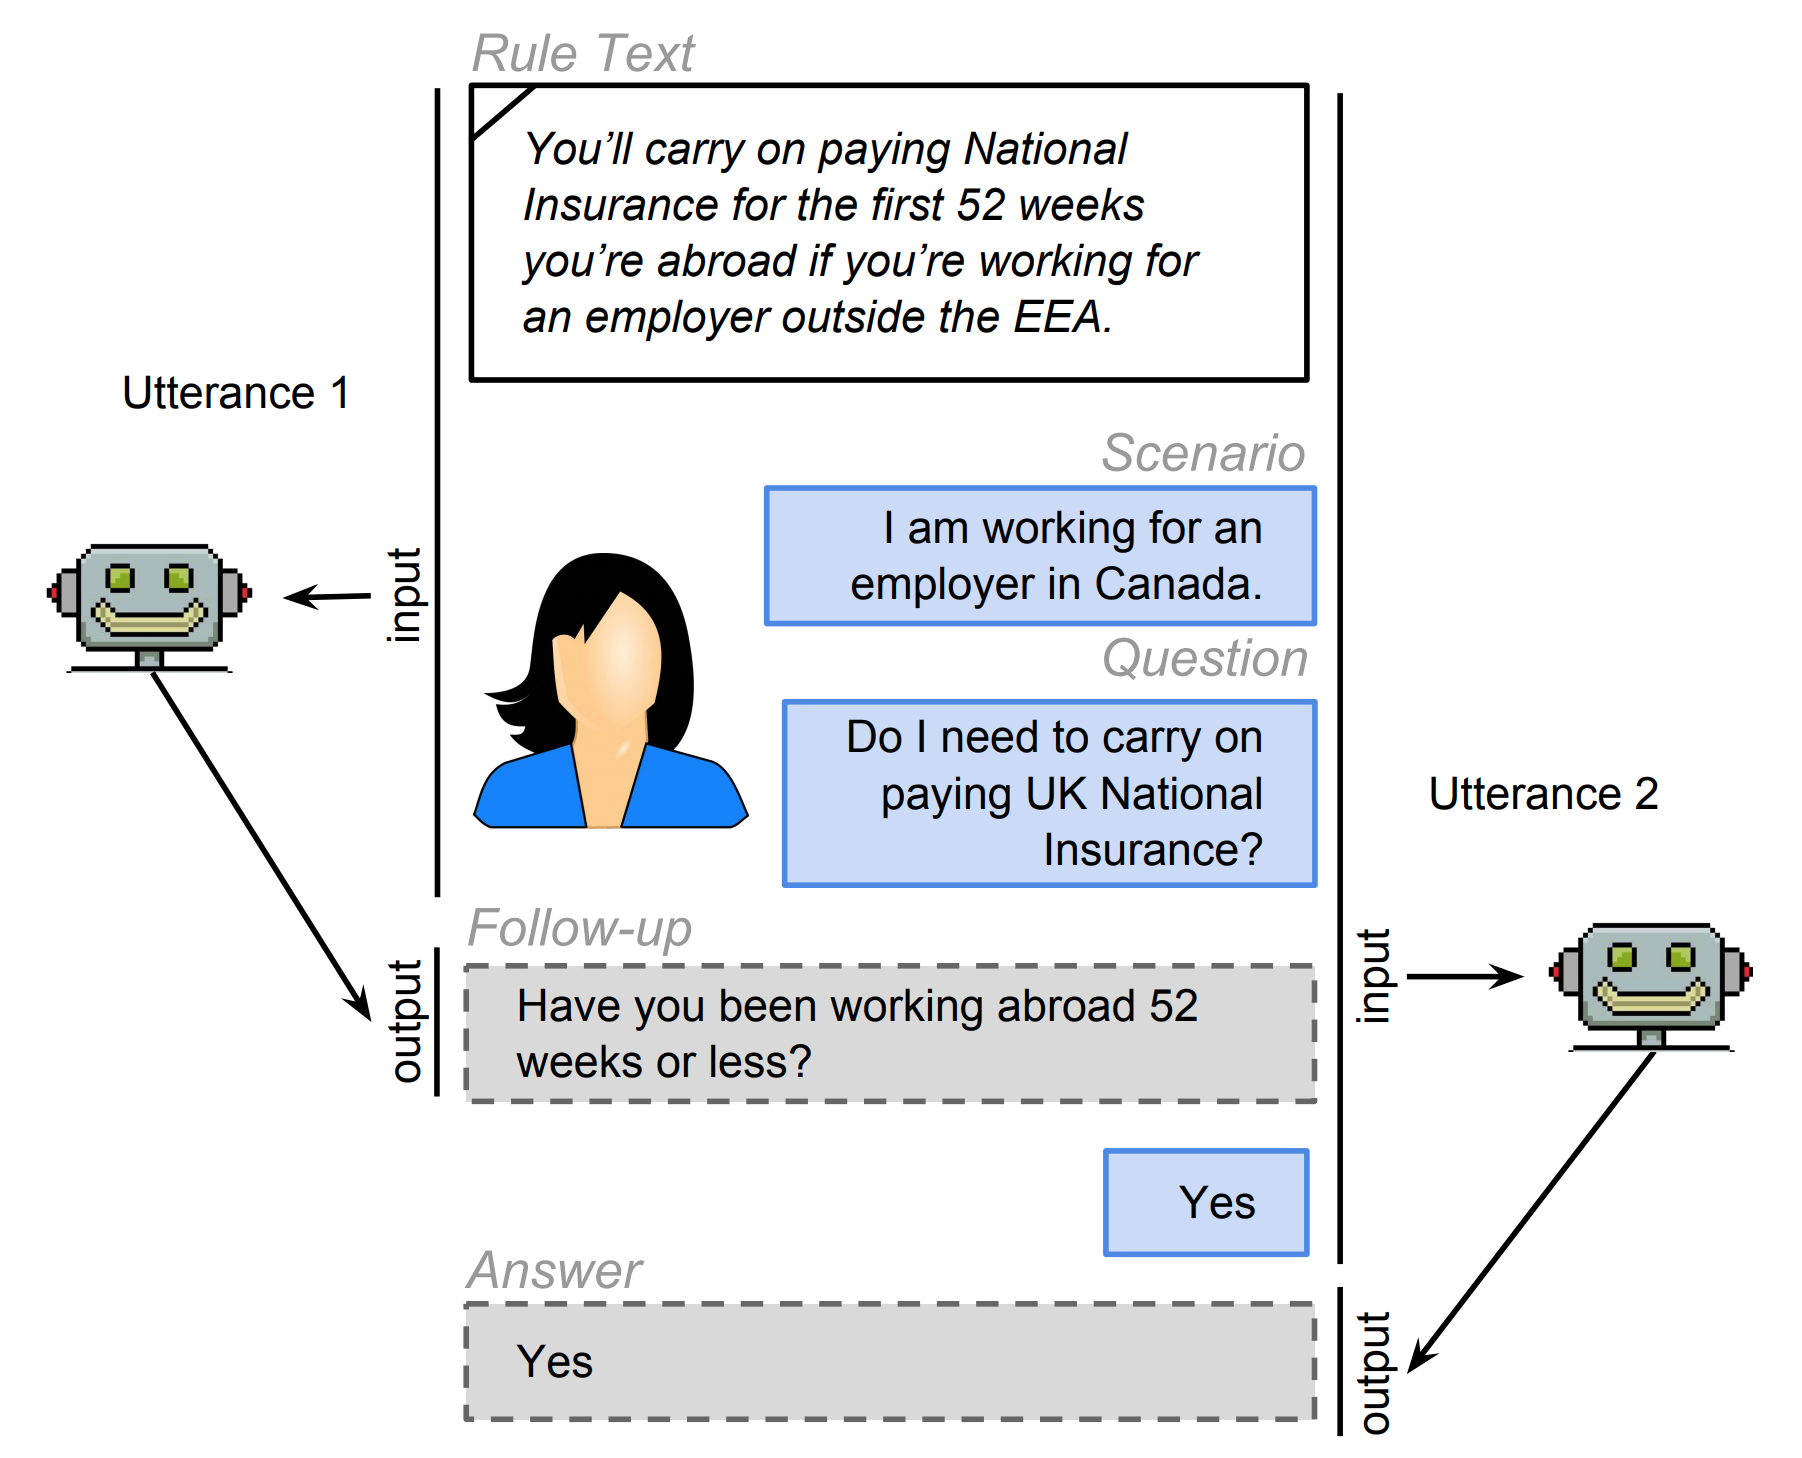
ShARC: Shaping Answers with Rules through Conversation
A collection of 32k task instances based on real-world rules and crowd-generated questions and scenarios requiring both the interpretation of rules and the application of background knowledge.
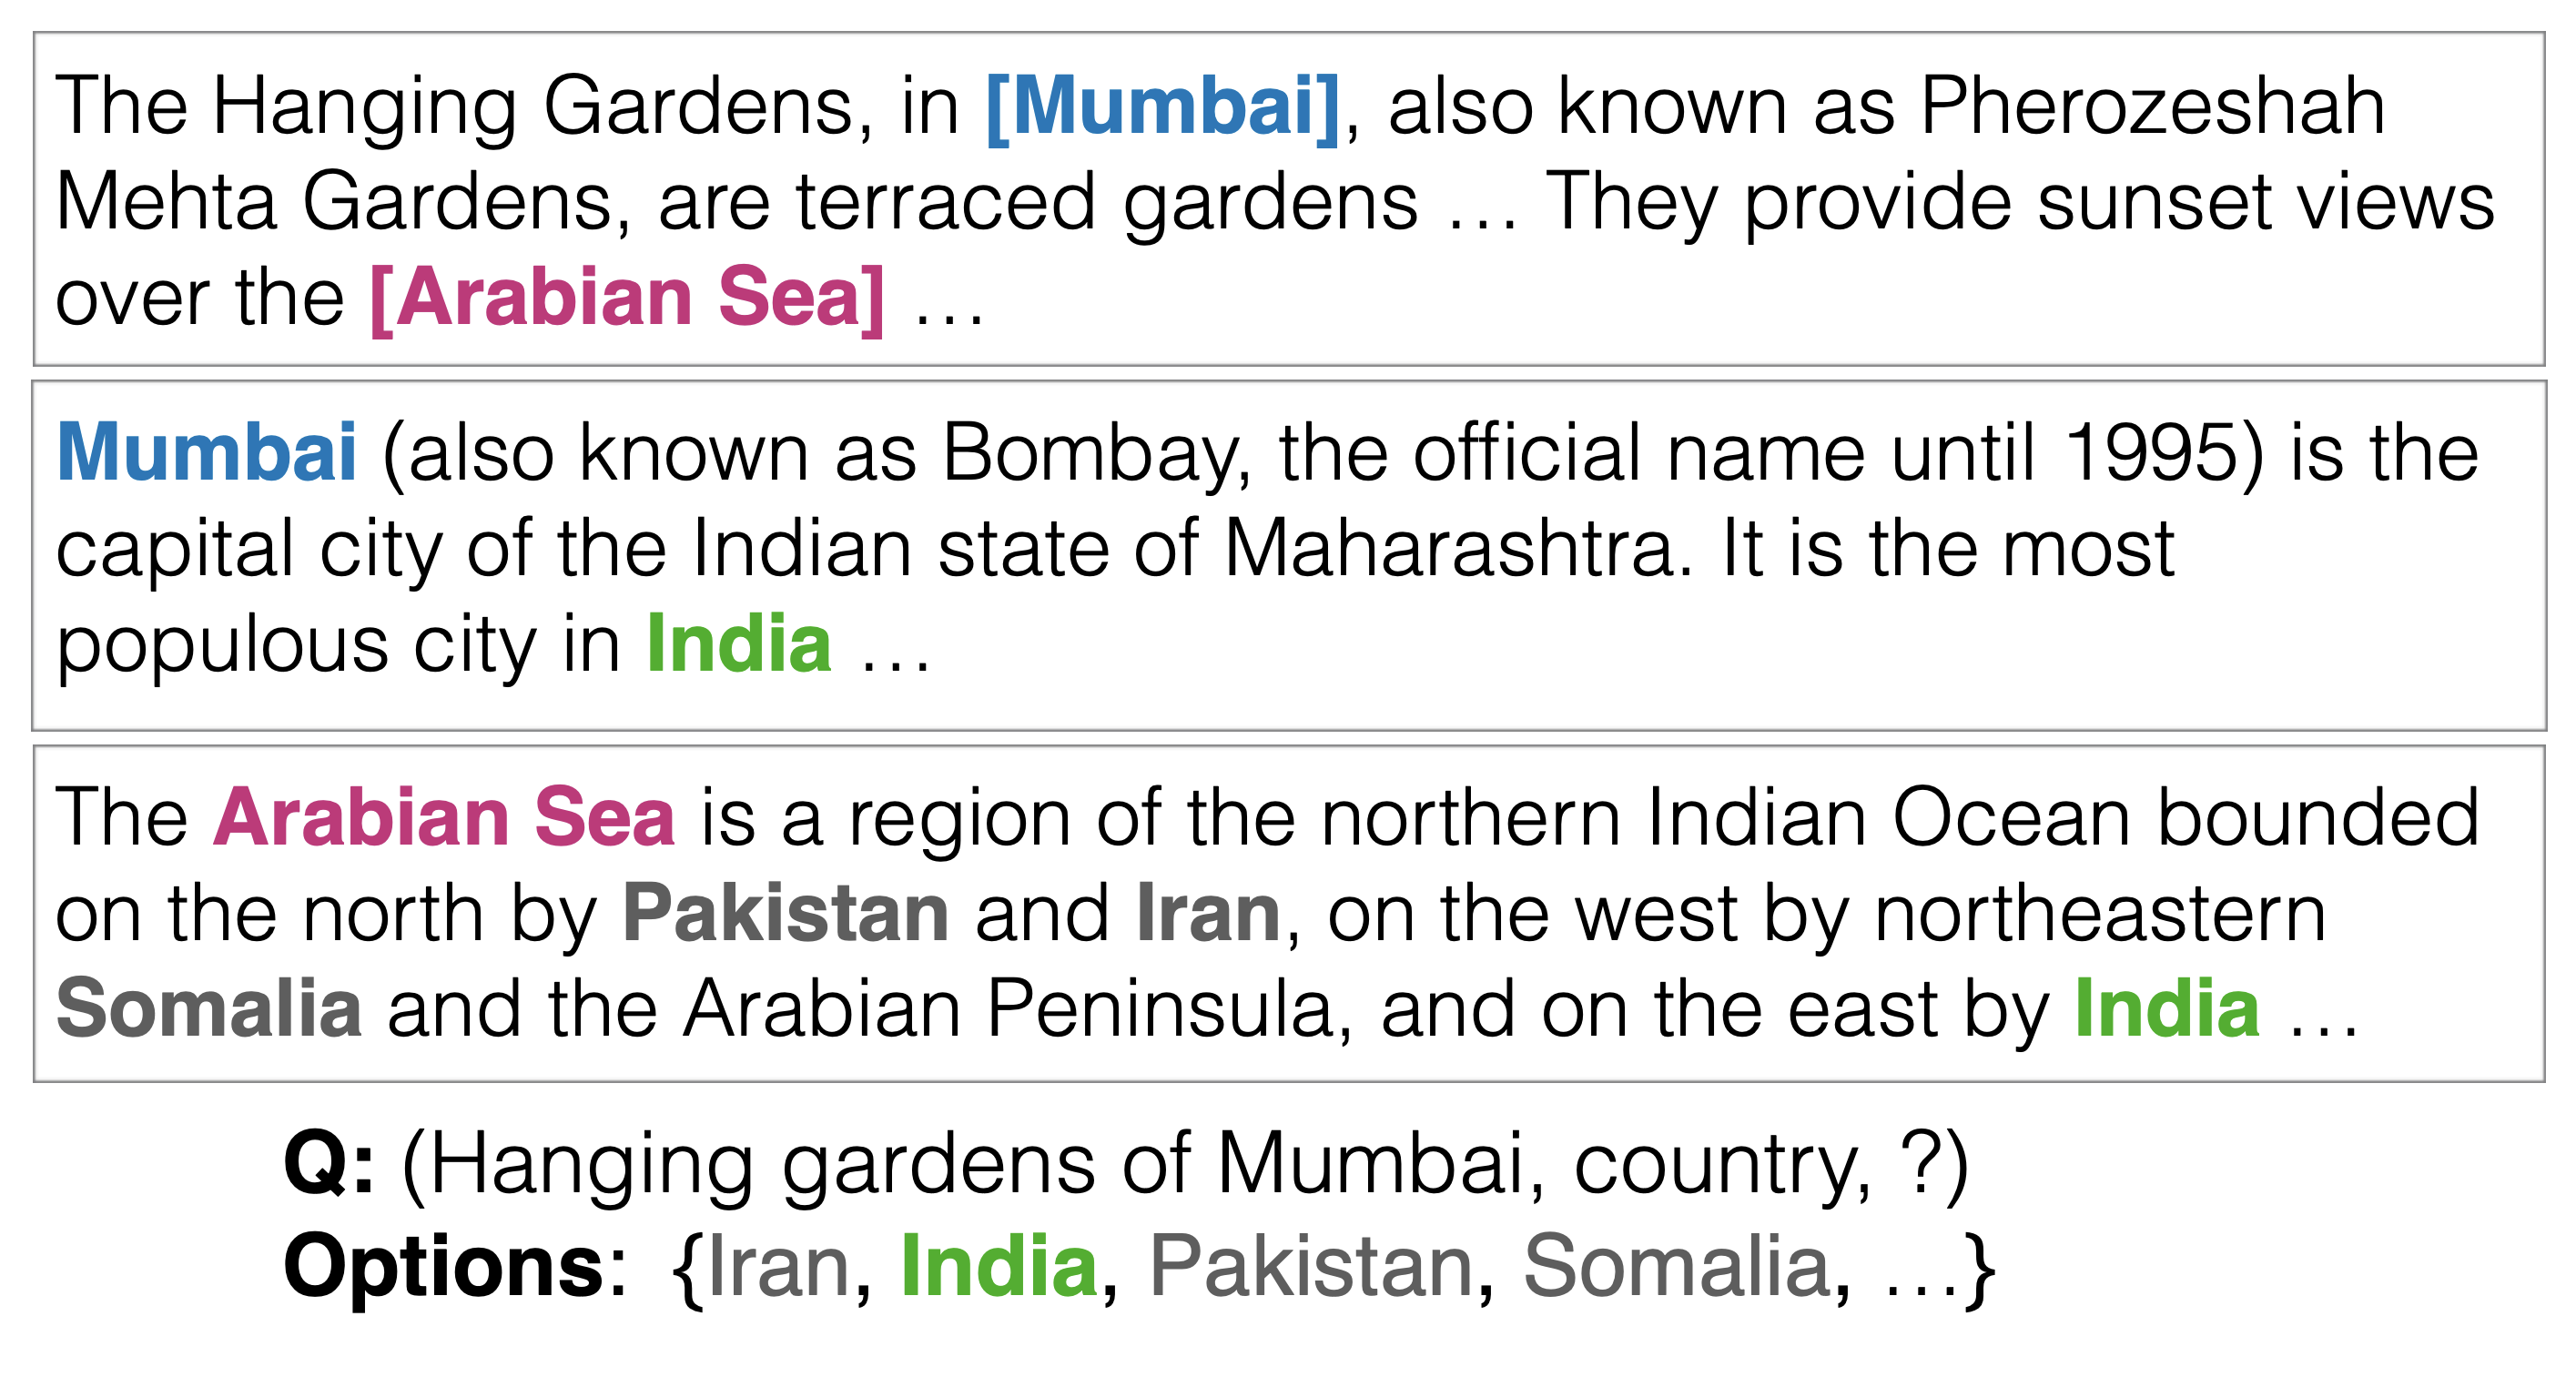
WikiHop & MedHop (QAngaroo)
Multi-hop question answering datasets from two different domains, designed to enabe models to combine disjoint pieces of textual evidence.